Tools Built
Custom Evaluation Infrastructure
Purpose-built tools for annotating, tracking, and comparing evaluation results.
Building a recipe generator that does not hallucinate — and proving it with systematic evaluation methodology learned from the Maven Evals course.
My role: personal project. I built the generator and the evaluation infrastructure.
A precision nutrition recipe assistant that generates accurate, goal-aligned recipes — backed by rigorous evaluation.
NalaBheem is an AI-powered recipe assistant that generates nutrition-precise recipes tailored to specific fitness goals: weight loss, muscle gain, or maintenance. Named for Nala, the legendary cook of the Mahabharata, and Bhima, its strongman, it enforces strict macro targets, requires ingredient qualifiers, and validates nutrition calculations.
But building an AI that gives accurate nutrition advice is only half the challenge. The other half? Proving it actually works.
This project applies rigorous evaluation methodology learned from a Maven AI Evals course — combining open coding of 100+ traces, custom error taxonomies, and systematic comparison of manual vs. automated evaluation to surface real issues.
From raw AI outputs to systematic quality measurement — a methodology that surfaces real issues, not just vibes.
Created a precision nutrition bot with strict macro targets, ingredient qualifiers, and goal-specific constraints.
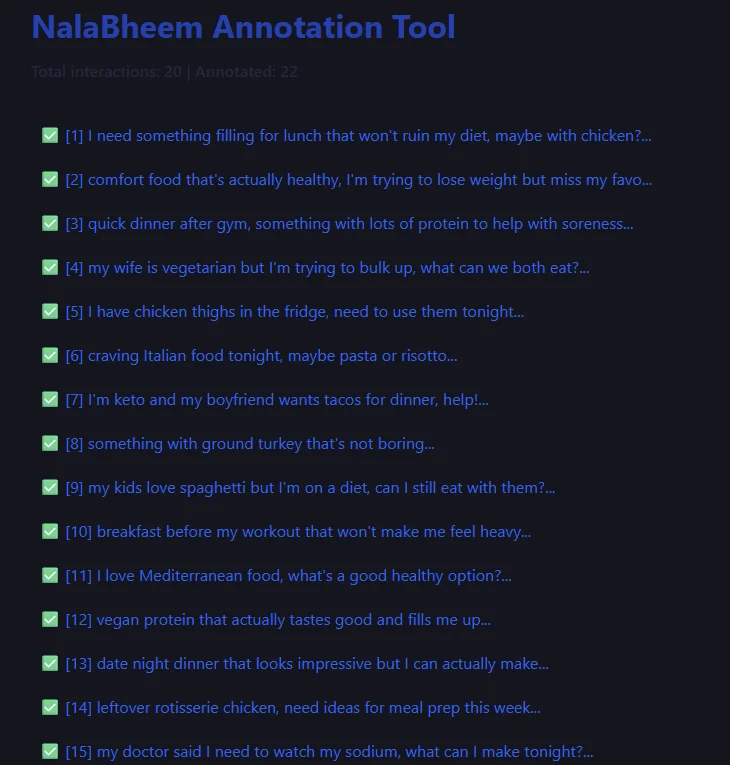
Manually reviewed 100+ bot responses, identifying patterns and failure modes without predefined categories.
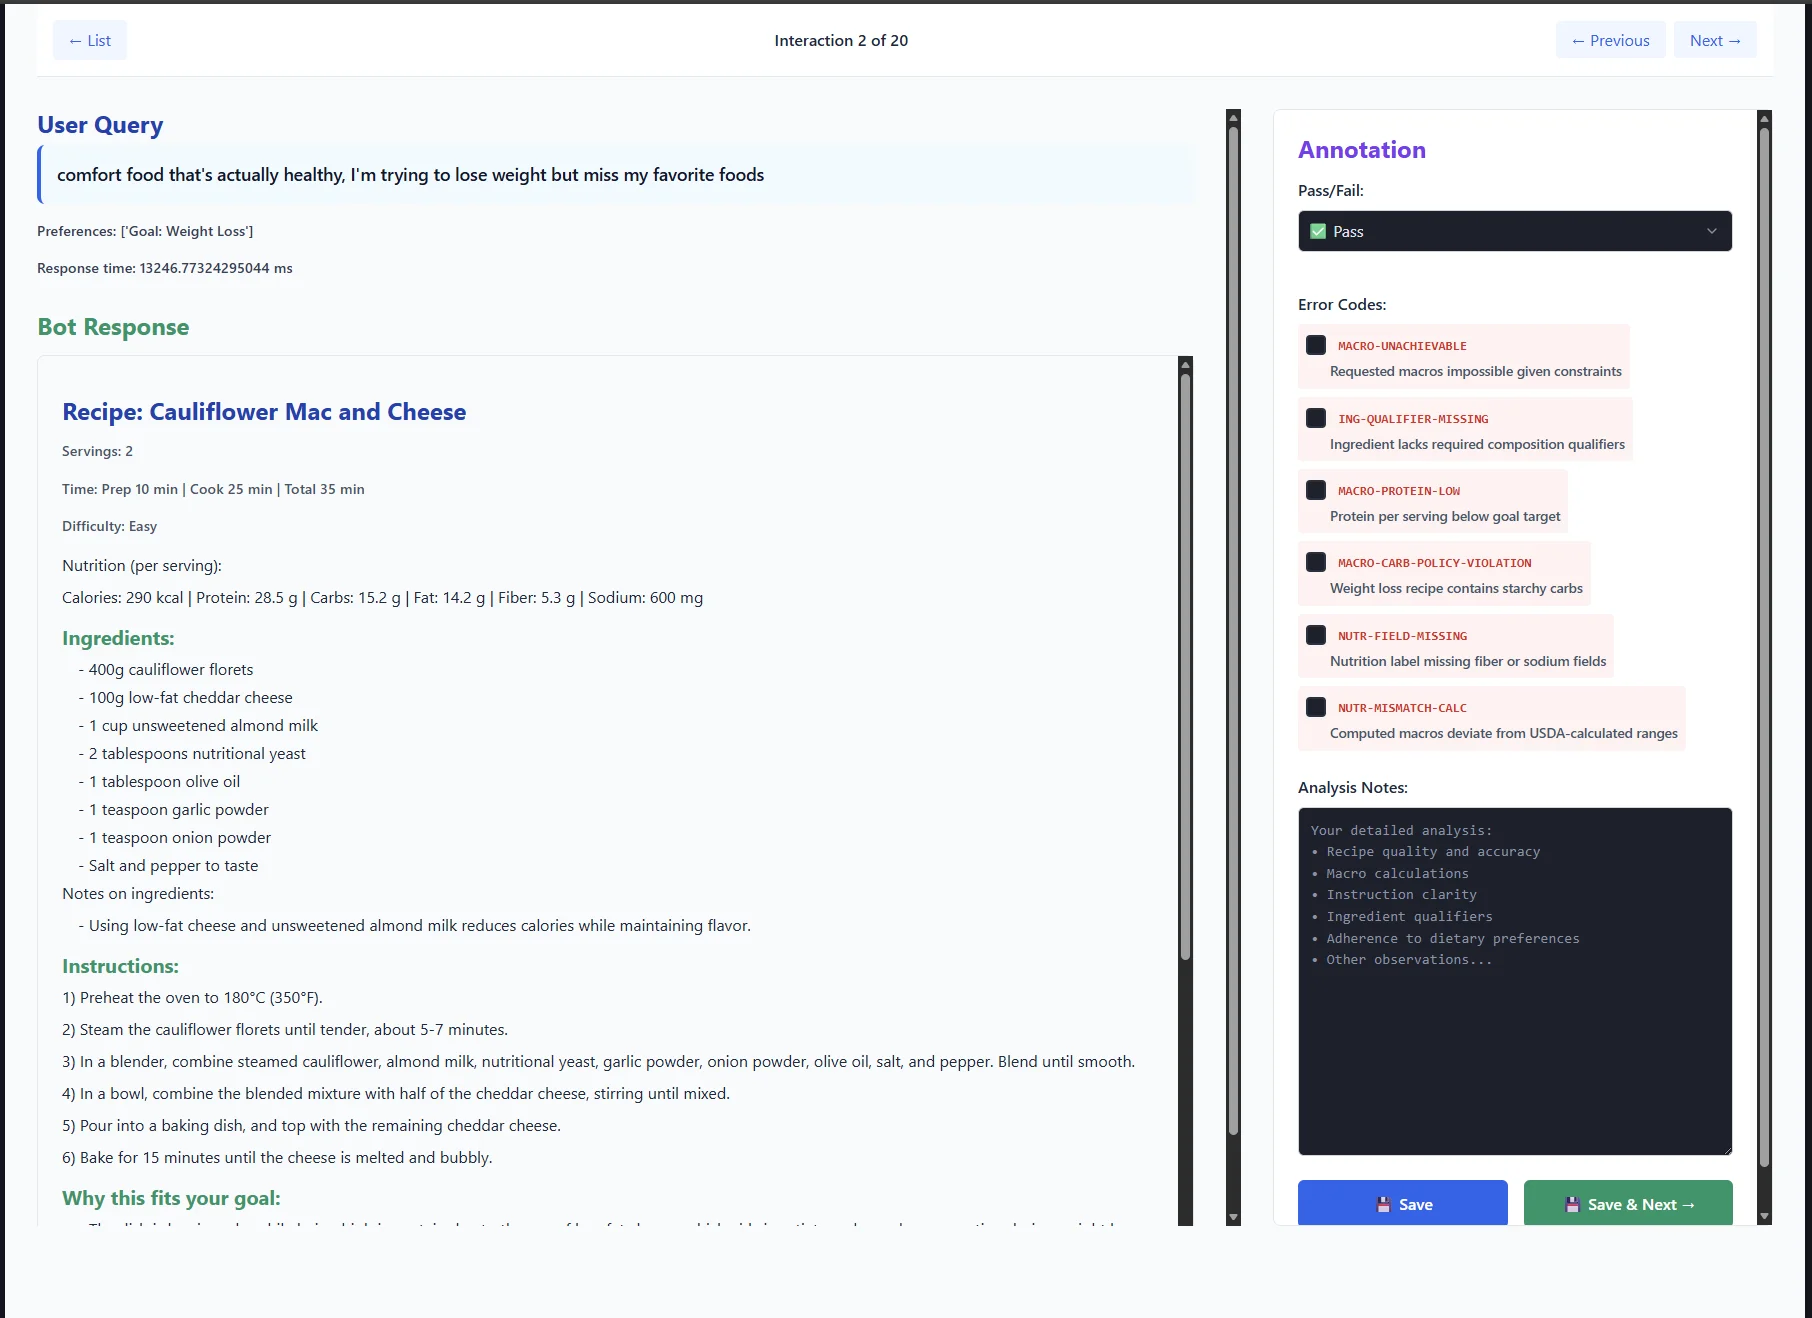
Distilled observations into 6 precise error codes covering macros, ingredients, and nutrition accuracy.
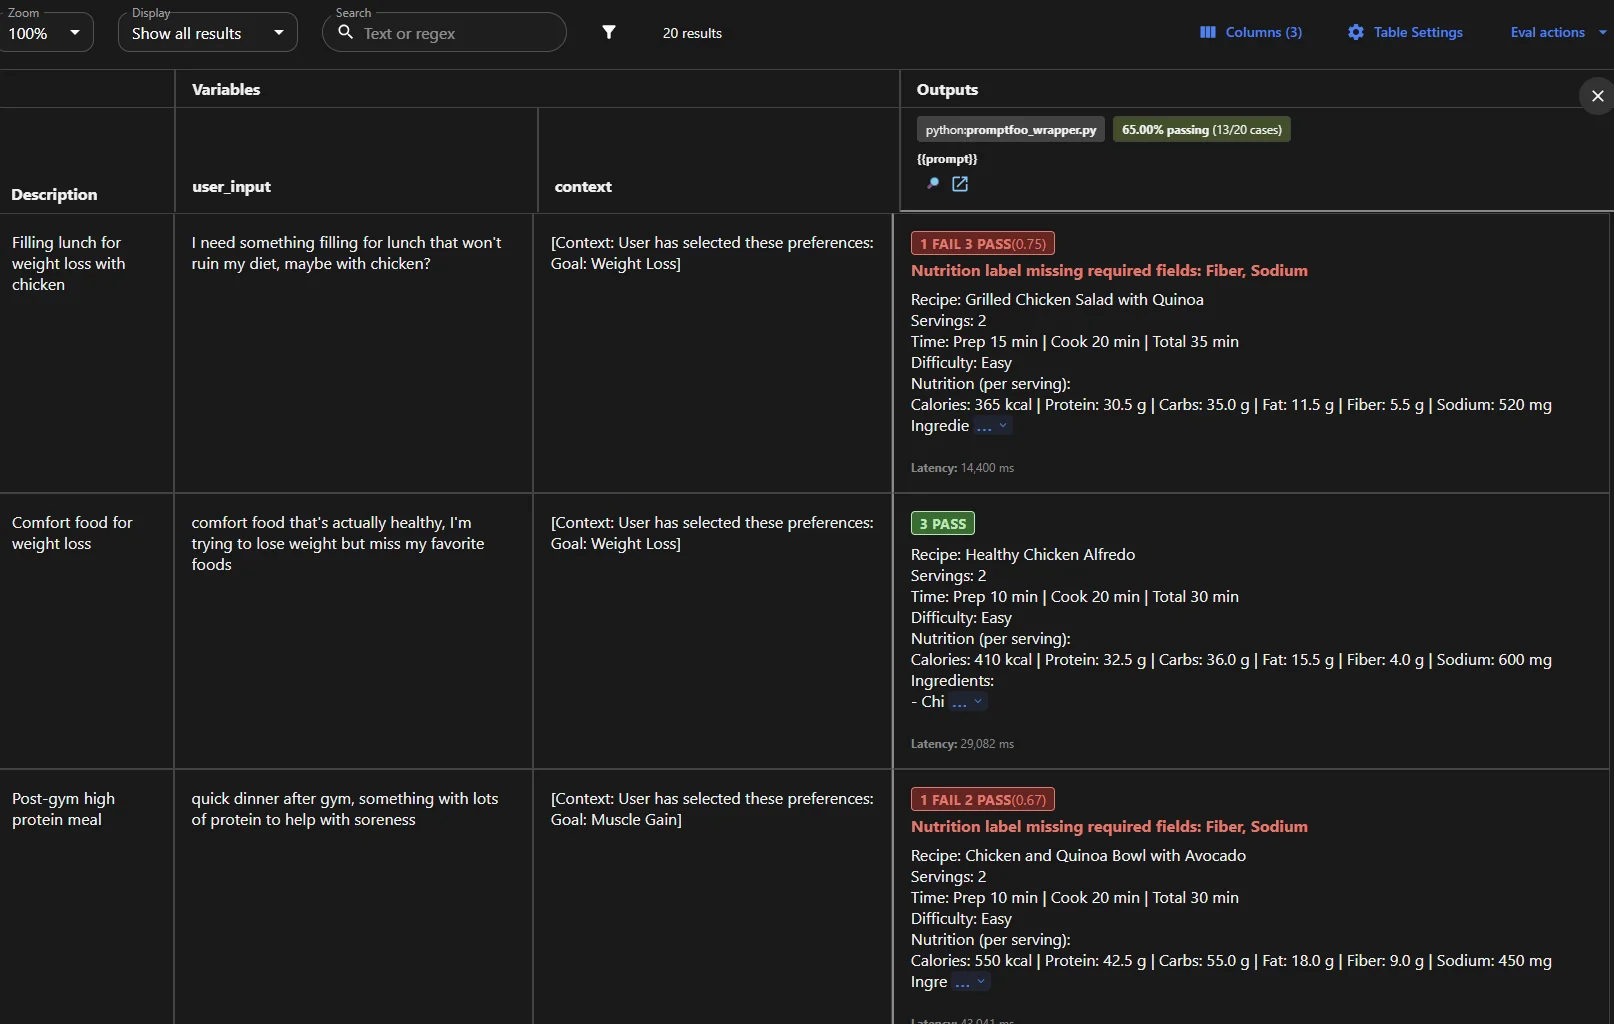
Used PromptFoo for automated evals, then compared against manual annotations to measure evaluator quality.
A precision-focused taxonomy that catches real nutrition failures — not just formatting issues.
Triggered when user constraints make the requested macros mathematically impossible to achieve.
Ingredient lacks required qualifiers: fat %, lean %, skin-on/off, raw vs cooked, drained weight.
Protein per serving falls below the goal minimum: <40g weight loss, <50g muscle gain, <30g maintenance.
Weight-loss recipe includes starchy carbs by default when the policy prohibits them.
Fiber or sodium is missing from the required nutrition panel output fields.
Computed macros deviate from USDA reference data: ±5% for macros or >±20 kcal for calories.
Purpose-built tools for annotating, tracking, and comparing evaluation results.
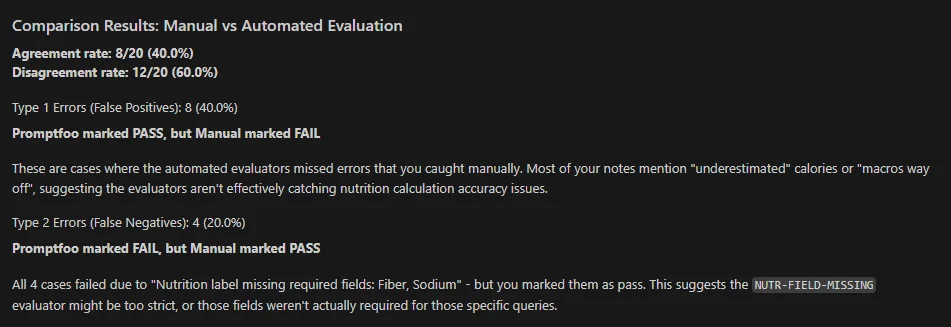
The evaluation process is working — it is catching real issues that need to be fixed.
PromptFoo PASS, Manual FAIL: Automated evaluators missed nutrition calculation accuracy issues. Notes mention "underestimated calories" and "macros way off" — these are real issues in the prompt that need correction.
PromptFoo FAIL, Manual PASS: All flagged for "Nutrition label missing required fields: Fiber, Sodium" — the NUTR_FIELD_MISSING evaluator may need recalibration for context-specific requirements.
The evaluation methodology behind this project came from the Maven Evals course. The bot itself is not currently hosted.